Claude Messages Count Tokens API Application and Usage
The Claude Messages Count Tokens API can calculate the number of input Tokens in a Message without actually creating a message, including Token counts for tools, images, documents, and other content. This is very useful when you need to estimate costs or check whether the input exceeds the model context limit.
This document mainly introduces the usage process of the Claude Messages Count Tokens API.
claude-fable-5-2 currently does not provide the Count Tokens interface. The final usage of generated requests can be viewed from usage in the Messages response; do not use counting results from other models as a substitute for the accurate usage of this model.
¶ Application Process
To use the Claude Messages Count Tokens API, first go to the 品格AI Console to obtain your API Token and keep it for later use.
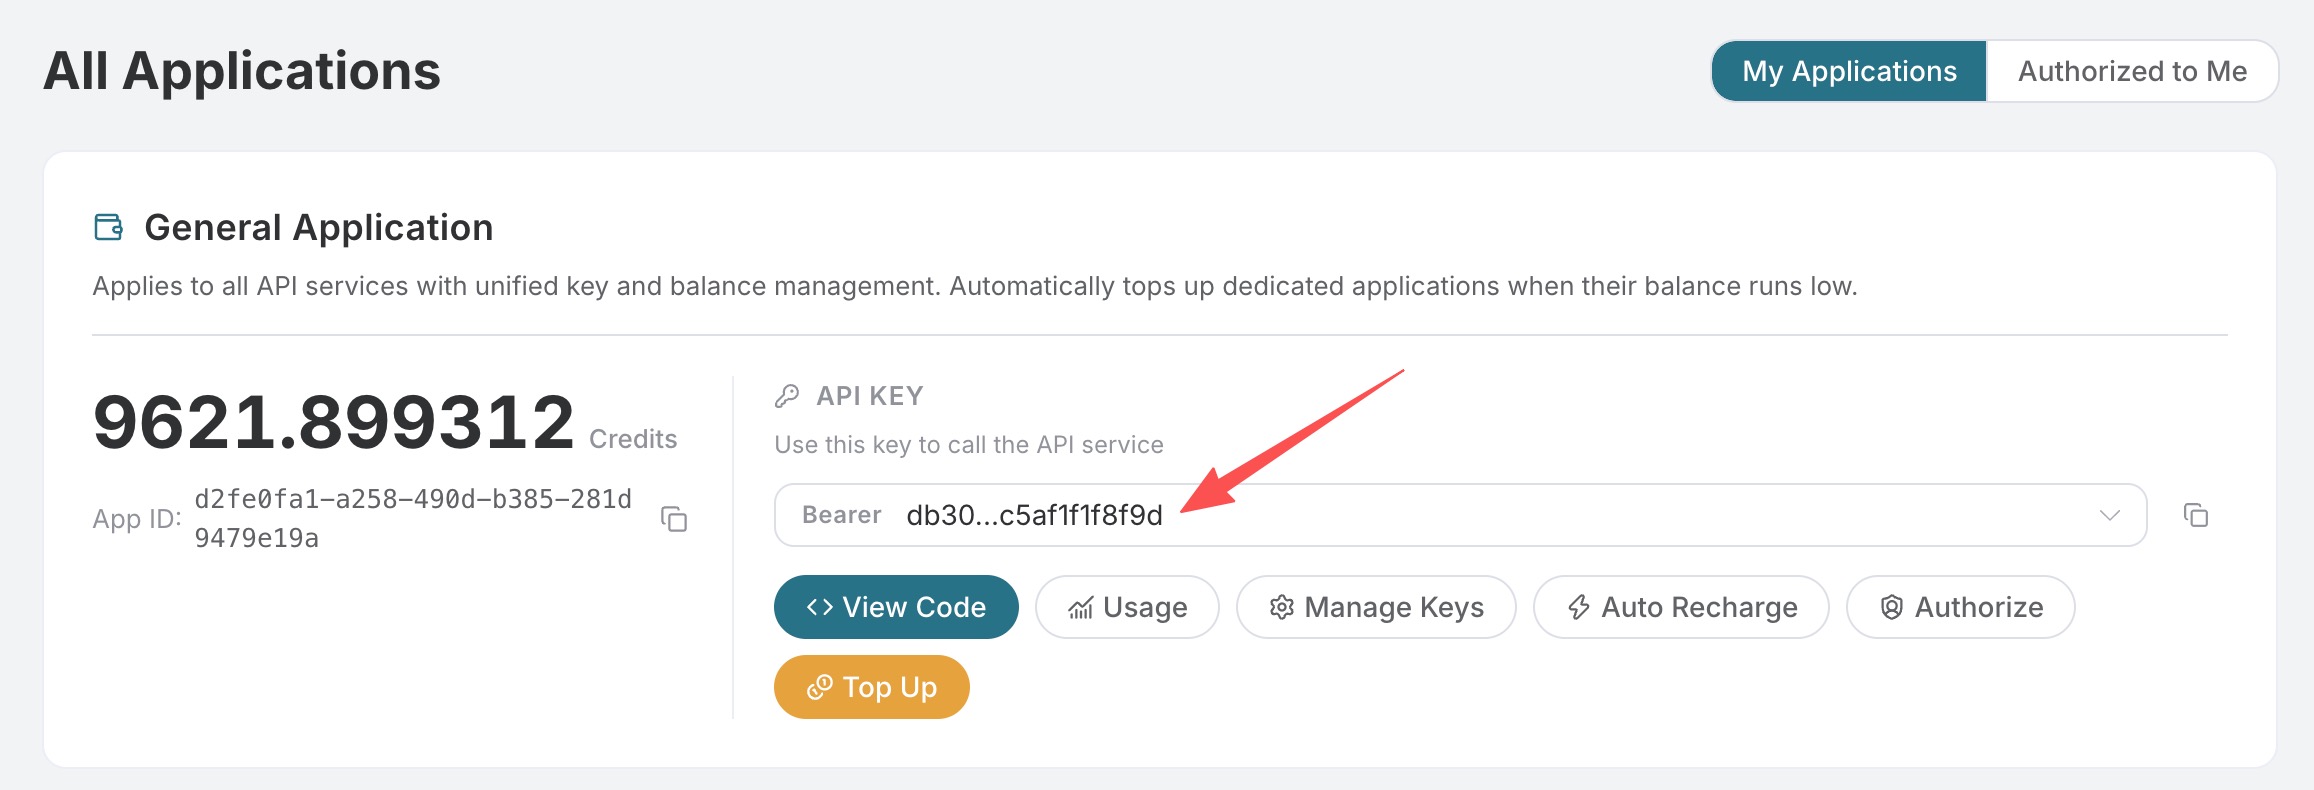
If you have not logged in or registered yet, you will be automatically redirected to the login page and invited to register and log in. After completion, you will automatically return to the current page.
One API Token can call all platform services; there is no need to apply separately for each service. Your first application includes free credits for a free trial; when credits are insufficient, you can recharge your general balance in the Console.
📘 Full documentation: Claude Messages Count Tokens API →
¶ Basic Usage
The request path for the Claude Messages Count Tokens API is /v1/messages/count_tokens, which is consistent with the official Anthropic API. We need to provide at least two required parameters:
model: Enter the complete model ID from this interface's model list, and use the same model for subsequent Messages requests.messages: The input message array, where each message containsrole(role) andcontent(content).
Common optional parameters:
system: System prompt, which is included in the Token count.tools: Tool definitions, which are included in the Token count.thinking: Extended thinking configuration.tool_choice: Tool selection configuration.cache_control: Top-level or content block-level cache control configuration.
messages, system, tool call replay, URL images, and document/PDF content blocks use the same stable request structure as the Messages API.
¶ cURL Example
curl -X POST 'https://api.pingesoft.com/v1/messages/count_tokens' \
  -H 'accept: application/json' \
  -H 'authorization: Bearer {token}' \
  -H 'content-type: application/json' \
  -d '{
    "model": "claude-fable-5-1",
    "messages": [
      {
        "role": "user",
        "content": "Hello, Claude"
      }
    ]
  }'
¶ Python Example
import httpx

url = "https://api.pingesoft.com/v1/messages/count_tokens"
headers = {
    "accept": "application/json",
    "authorization": "Bearer {token}",
    "content-type": "application/json",
}
payload = {
    "model": "claude-fable-5-1",
    "messages": [
        {
            "role": "user",
            "content": "Hello, Claude"
        }
    ],
}
response = httpx.post(url, headers=headers, json=payload)
print(response.json())
Example response:
{
  "input_tokens": 11
}
¶ Using the Anthropic SDK
The Claude Messages Count Tokens API accepts the stable request structure of the Anthropic SDK and can be called through the anthropic library. The interface counts input Tokens based on the selected model and can be used to check input size before sending a Messages request.
from anthropic import Anthropic

client = Anthropic(
    api_key="{token}",
    base_url="https://api.pingesoft.com",
)

result = client.messages.count_tokens(
    model="claude-opus-4-8",
    messages=[
        {
            "role": "user",
            "content": "Hello, Claude"
        }
    ],
)
print(result.input_tokens)
¶ Token Counting with Tools
If your request includes tool definitions, these tools are also included in the Token count:
result = client.messages.count_tokens(
    model="claude-opus-4-8",
    messages=[
        {
            "role": "user",
            "content": "What is the weather in San Francisco?"
        }
    ],
    tools=[
        {
            "name": "get_weather",
            "description": "Get the current weather in a given location",
            "input_schema": {
                "type": "object",
                "properties": {
                    "location": {
                        "type": "string",
                        "description": "The city and state, e.g. San Francisco, CA"
                    }
                },
                "required": ["location"]
            }
        }
    ],
)
print(result.input_tokens)
¶ Token Counting with a System Prompt
The system prompt is also included in the Token count:
result = client.messages.count_tokens(
    model="claude-opus-4-8",
    system="You are a helpful assistant that speaks Chinese.",
    messages=[
        {
            "role": "user",
            "content": "Hello"
        }
    ],
)
print(result.input_tokens)
¶ Notes
- This API only calculates the number of input Tokens and does not generate any model output.
- Token counting results can be used to estimate input size and check the context window; final billing is based on
usagein the actual Messages response. - Images, PDFs, tool definitions, system prompts, and thinking configurations are included in the result according to the input rules of the selected model.
- This API is completely free and does not consume any credits.